Development
Google figures out how to watermark AI-designed proteins
September 30, 2026 Development Source: Ars Technica
Share this article
It’s pretty easy to see how this can work with subtle differences in things like the colors of a photo. It’s a whole lot harder to see how you can do it with a protein.
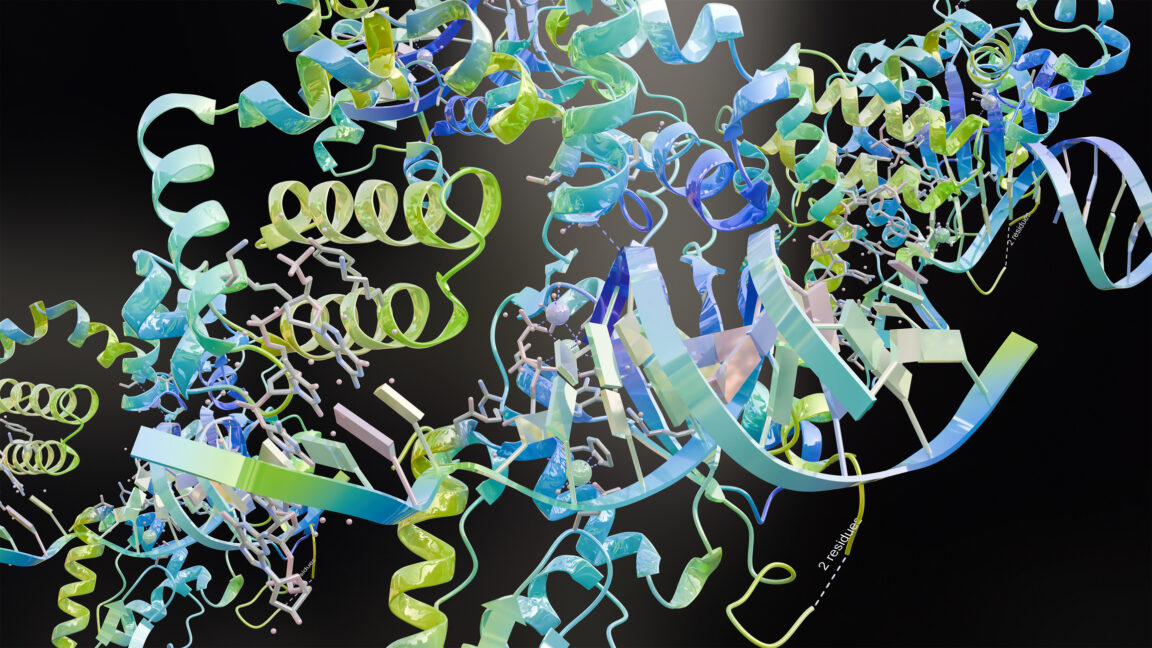
Proteins are composed of only 20 amino acids, any of which could be essential for structural integrity or catalytic activity. While some of these amino acids are chemically similar (like leucine and isoleucine), others have opposite charges. Many proteins have significant regions where limited changes to their amino acid sequence are tolerable and other areas where even a slight deviation from the existing sequence inactivates the protein.
Proteins are also small. While images often contain millions of pixels, proteins containing 500 amino acids are fairly large. That’s a lot less raw material to hide any sort of signal in.
So it wasn’t clear the SynthID tech would work; it might be unable to hide sufficient signal in a typical protein, or, if it crammed in enough information to create a functional watermark, the resulting proteins might be inactive. The only way to find out was to try it.
To better understand how the system works, it helps to know a bit about protein chemistry. Amino acids have a constant section primarily made of two carbon atoms linked to a nitrogen. A protein is made by linking up a series of these constant sections to form a long chain called a backbone. Each amino acid also has what is called a side chain hanging off it. These can range in complexity from a single hydrogen atom to large ring structures; the side chains can be basic hydrocarbons, acids, bases, and more.
One way to think about this is that, when the system comes across a location where a set of chemically related amino acids will all work (like leucine/isoleucine/valine or serine/threonine), it will use one that’s consistent with the watermark when possible. Another way to look at the process, suggested by one of the people involved in developing the system, is that it searches through the space occupied by functional proteins for the subset that happens to have a sufficient number of watermark amino acids.
As a result, the watermark is randomly distributed across the entire length of the protein, and detecting one isn’t a simple yes-or-no question. You have to scan the whole sequence, knowing the key, and measure how often the amino acids suggested by SynthIDBio actually appear in the final sequence. Google has also developed the software needed to do this.
The question, then, is whether watermarked proteins are functional. The team used the system to design proteins that physically interact with key natural proteins previously targeted with AI designs. And the watermarked versions worked just fine, binding the intended targets. This isn’t as rigorous a test as finding a catalyst, but it suggests that there’s no reason to expect serious problems in more complicated design tasks.
So as long as a protein is long enough, the system can detect a watermark. How might that be useful? Again, it comes down to biosecurity. When someone orders DNA sequences, the people who make the DNA normally screen the sequence for its ability to encode portions of viruses, toxic proteins, and other similar threats. Right now, however, when they see a protein that doesn’t look similar to anything we already know about—something that’s potentially true for any AI-designed proteins—they can’t assess its threat.
Google envisions its system as a way to give DNA synthesizers greater confidence when it comes to these proteins. If they’re given a set of keys from trusted organizations, like universities or major biotech companies, they can quickly determine whether an unknown protein is an AI design from a trusted source. This should let them focus their attention and resources on evaluating the things that aren’t trusted—specifically those things that look like AI designs but don’t come from a trusted source.
In other words, it doesn’t guarantee the security of DNA orders, but it simplifies the threat-screening process.
The team behind the work has highlighted several potential holes. For starters, the whole system is only as secure as the system used to distribute and maintain the keys used for watermarking. Very short proteins can potentially incorporate too few watermark amino acids to be identified. And it’s possible to pad the watermarked sequence with something that lacks it—think fusing the AI-designed protein with a natural fluorescent protein—which might dilute the watermark.
There are also a number of AI-based protein design software packages that don’t rely on ProteinMPNN. Some, but not all, use a similar “one amino acid at a time” approach that should integrate well with SynthIDBio. So until Google figures out how to handle other forms of integration, not everyone will be able to watermark the proteins they’re designing.
And since watermark identification is done on a statistical basis, how you set the cutoff makes a big difference in terms of false positives and false negatives.
It’s not clear this will be especially useful in practice, at least in its original form. But it’s pretty interesting that it works at all. And it’s nice to know that at least some people in the AI industry are thinking about how to limit risks.
Nature, 2026. DOI: 10.1038/s41586-026-10965-y (About DOIs).